

Microsoft Copilot or custom enterprise AI: which is better?
The deciding question is not Copilot versus a custom build, but where the context comes from. Microsoft Copilot is the obvious choice for document work in Outlook, Teams and Word. For questions like "How do we handle this case?" it answers from the state of your repositories. A custom build on the same sources has the same problem. Usually the third option is right: keep Copilot and feed it through a validated knowledge layer.
- Context beats model. Answers are only as good as the sources behind them.
- A custom build does not fix it. Your own pipeline on unmaintained sources gives the same quality.
- Feed Copilot better. A knowledge layer validates what exists and captures what is missing.
The question is usually framed wrongly. It is not: Copilot or something of our own? It is: where does the context come from that the answer is built on?
Whoever settles that has already made the architecture decision. Whoever skips it buys a good model and still gets unusable answers.
What Copilot solves well
In a Microsoft landscape Microsoft Copilot is the obvious choice, and for good reasons. It sits where the work happens: in Outlook, Teams, Word, Excel. Permissions come from your existing model, adoption needs no separate project, and for tasks around documents and communication the benefit is immediate. Summarising mail, structuring minutes, analysing tables.
For that class of task the question of an alternative is not relevant at all.
Where it tips over
It gets critical with a different kind of question. Not summarise this document, but how do we proceed in this case?
Copilot answers that from what it finds: your files, your mail, your SharePoint content. In other words, from the state of your repository. And in almost every company that state is exactly what years of growth made it: partly stale, partly contradictory, and in essential parts not present at all. The four diagnostic questions for that are set out in the piece on the Confluence alternative.
42 percent of job-related knowledge is documented nowhere (Panopto/McKinsey). What is not filed cannot be found by any assistant. It will answer anyway, because it is designed to phrase things plausibly.
Your AI systems are only as good as their context. If the context is SharePoint, the answers are as good as SharePoint.
Why building your own has the same problem
At this point the reflex is often to build: own model, own RAG pipeline, full control.
That settles questions of hosting, data sovereignty and cost. It does not settle the context problem. A self-built pipeline pointed at the same unmaintained sources delivers the same answer quality, only with more effort under your own accountability. What such projects concretely fail on is set out in the piece on RAG architecture for enterprise.
The measurable consequences are independent of the build: 95 percent of AI pilots show no measurable ROI (MIT NANDA, 2025). 47 percent of enterprise AI users made at least one important business decision based on hallucinated content. And 4.3 hours per person per week on verification, roughly 14,200 dollars a year.
The last figure is the bitter one: you pay for acceleration and finance re-checking.
The third option, which is usually the right one
Do not replace Copilot. Feed Copilot better.
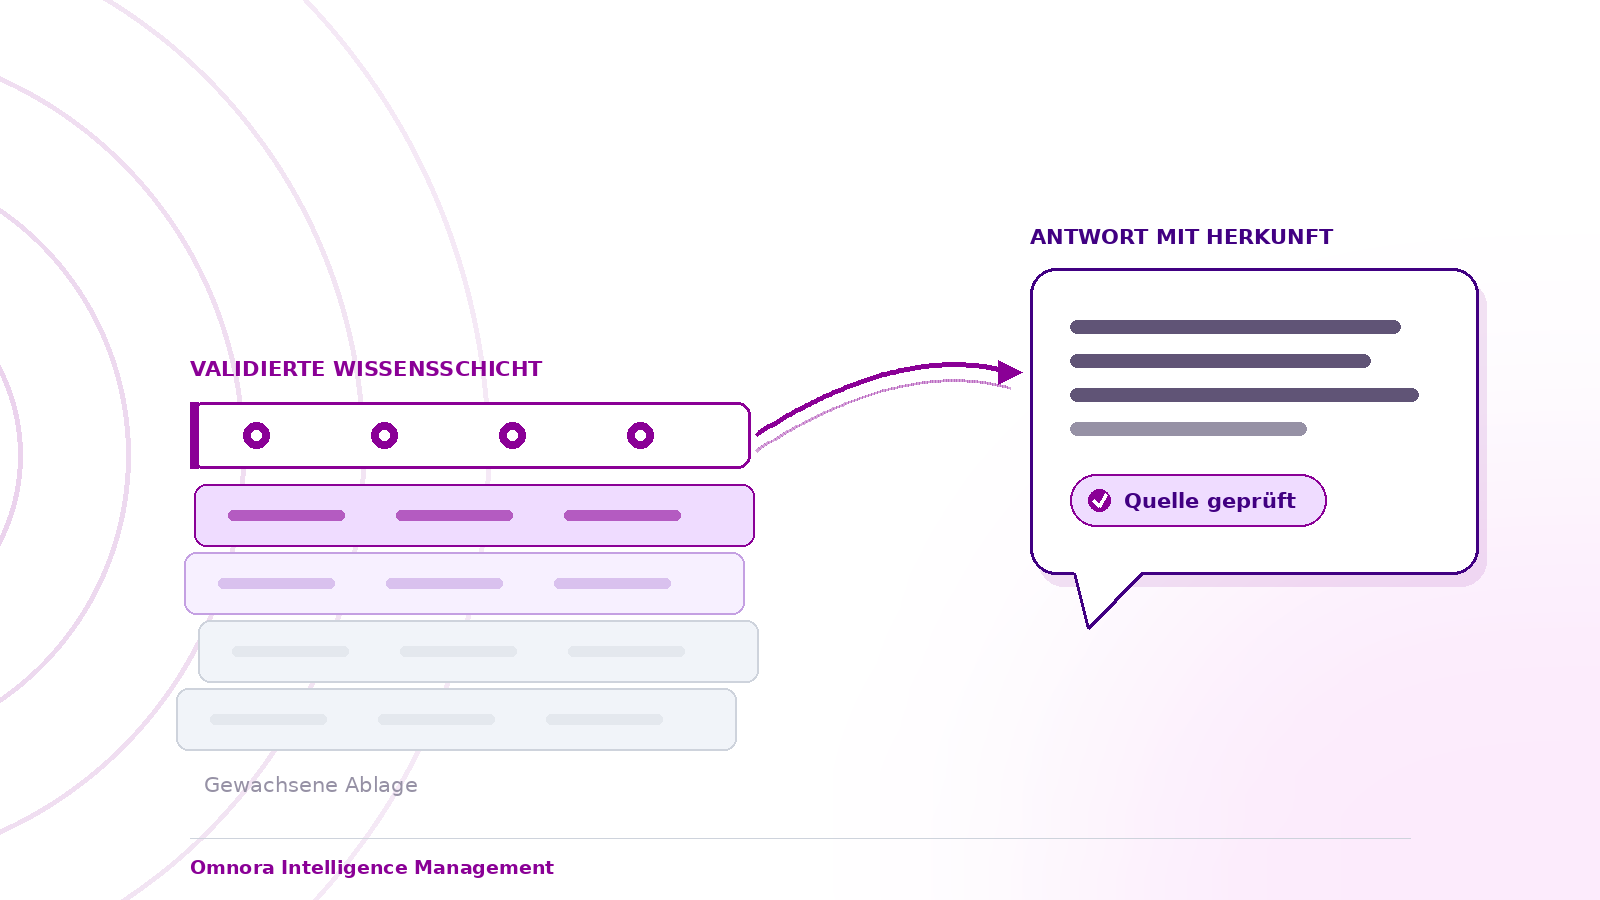
In practice that means a knowledge layer in front of it, producing reliable context from sources and from people, and delivering that context to your existing front end. Via RAG API, REST API and MCP server, with SharePoint delivery and Copilot as a context consumer.
This layer does two things an assistant alone cannot.
1 It validates
Every knowledge object gets an owner, a validity date, a verification status and provenance. Contradictions are resolved along five dimensions: correctness, currency, relevance, freedom from conflict, completeness. That lets retrieval prioritise rather than guess.
2 It captures what is missing
AI-supported expert interviews get decision logic, exceptions and heuristics out of people's heads. That is the part no search finds, because it was never written.
Only under that condition does the documented effect apply: 40 to 71 percent fewer hallucinations through RAG with validated context (meta-analysis 2024). The qualifier validated is the entire point.
The decision matrix in four lines
- The task is document work and the sources are uncritical. Copilot alone is enough.
- The task is decision support and the knowledge exists documented and current. Copilot plus clean retrieval. You do not need a capture layer, you need order.
- The task is decision support and essential knowledge sits in people's heads. A knowledge layer with active capture, connected to Copilot. The most common case in manufacturing and regulated companies.
- Autonomous agents are meant to act, not only answer. Without a trust layer carrying provenance this is not defensible. An agent acting on textual similarity scales errors.
What counts additionally in Europe
Two regulations are in force: EU AI Act Article 4 on AI literacy obligations since February 2025, NIS-2 since December 2025. Both concern traceability and governance, not only hosting.
Relevant checkpoints: EU hosting on Azure with data centres in Germany, GDPR compliance, TISAX assessment, no use of customer data for model training, complete and demonstrable deletion, role-based access control with an audit trail.
And a risk that often stays under the radar: over 50 percent of employees use private GenAI for work without oversight (Gartner, February 2026). As long as the internal route gives worse answers than the private tool, governance loses to convenience.
The test before the investment
Take ten questions that regularly escalate in your operation. Real questions, not demo questions. Put them to your current assistant and have the answers rated by the respective subject-matter experts: correct, incomplete, wrong.
Then count how many of the wrong and incomplete answers were down to the information not being documented anywhere. That share is your context problem. No change of model will solve it.
If you want to run this through with real questions: bring the ten questions along and we will go through them together.
How Omnora captures tacit expertise and makes it usable for your AI via AI chat and MCP server.
Building a corporate brain →Häufige Fragen
What is Microsoft Copilot good at?
Document work in a Microsoft environment: summarising, drafting and structuring in Outlook, Teams, Word and Excel. Permissions come from your existing model, and rollout needs no separate project. For these tasks an alternative is usually unnecessary.
Why does Copilot give wrong answers to process questions?
Because it answers from what it finds: files, emails, SharePoint. If those are outdated or contradictory, so are the answers. What was never documented it cannot find, yet it still phrases something plausible. 42 percent of job-related knowledge is documented nowhere (Panopto/McKinsey).
Does a custom AI with RAG solve the problem?
It solves questions of hosting, data sovereignty and cost, not the context problem. A self-built pipeline on the same unmaintained sources delivers the same answer quality, with more effort under your own responsibility.
What is a knowledge layer for Copilot?
A layer in front of the assistant that gives every knowledge object an owner, validity date, verification status and origin, and captures missing experience through interviews. It supplies context via RAG API, REST API or MCP to Copilot and other systems.
How do I test answer quality before investing?
Take ten real questions that regularly escalate, put them to your current assistant and have experts rate the answers. The share of wrong answers where the information was documented nowhere is your context problem.
Quellen
- Panopto / McKinsey: Share of job-related knowledge that is documented nowhere [Study]
- MIT NANDA (2025): Share of AI pilots without measurable ROI [Study]
- Meta-analysis (2024): Reduction of hallucinations through RAG with validated context [Study]
- Gartner (February 2026): Use of private GenAI accounts for work [Study]
- EU AI Act, Art. 4 (since February 2025); NIS-2 (since December 2025) [Regulation]